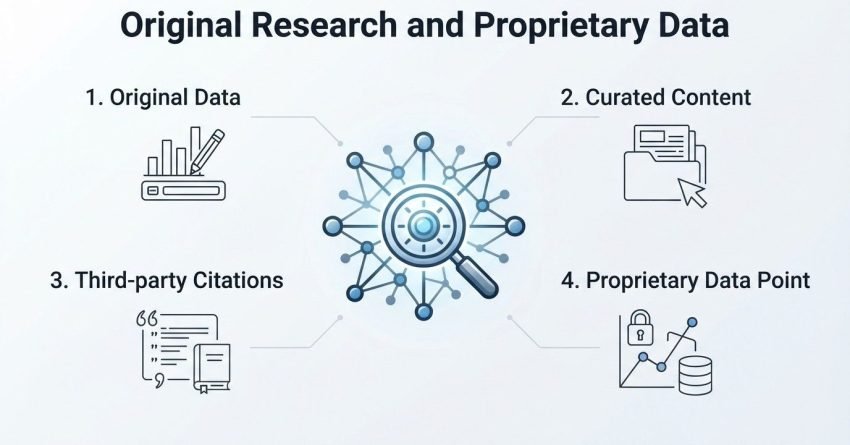
Original research is data, findings, or insights a business generates itself rather than referencing elsewhere, and it has become one of the strongest signals AI search systems use to decide which sources deserve a citation. I’ve watched this shift happen fast. Search engines and AI assistants are drowning in reworded, templated content, and they’re actively hunting for anything that adds a genuine new data point to the conversation.
Businesses that keep recycling existing information are becoming invisible in AI Overviews. The ones getting cited own a number nobody else has published yet.
This guide covers what counts as original research versus curated content, why AI systems are built to reward novel information, the practical formats proprietary data can take, and how to measure whether your research is actually earning citations. We’ll also cover the business case for investing here and the mistakes that quietly undermine credibility.
What “Original Research” Actually Means in an SEO Context
Original research, in an SEO context, is any data, finding, or insight that a business produces through its own surveys, internal analytics, testing, or direct observation rather than summarizing someone else’s work. I draw a hard line between three categories that get confused constantly: original data, curated content, and third-party citations.
Curated content takes existing information and organizes it better. It’s useful, but it’s not new. Third-party citation writing references someone else’s study, adds commentary, and republishes the same underlying number that a hundred other sites are also citing.
Original data is different because nobody else has it. A survey I run on my own client base, a benchmark I pull from internal analytics, a test I conduct, and the raw results I publish from these create information that didn’t exist in the public domain before I published it.
Content originality, as a ranking and citation factor, depends on whether a search system can trace a specific data point back to a single source. That traceability is exactly what curated content lacks.
Why AI Search Systems Are Built to Reward Novel Information
AI search systems reward novel information because their core function is answering a question with the single best available source, and a page repeating widely available information rarely qualifies as that source. Generative search results, including AI Overviews, work by synthesizing an answer and then attaching a citation to back it up.
That citation logic changes everything about content strategy. When a model has ten pages saying roughly the same thing, it needs a tiebreaker, and specificity is that tiebreaker.
A 2024 analysis by Ahrefs found that a large share of AI Overview citations point to pages containing original data points, unique statistics, or first-party research rather than generic advice content. The pages doing the citing are naming a number nobody else has.
This matters most in AI Overviews and LLM-based answer engines, where the system pulls a single fact, attributes it, and displays it directly to the user without requiring a click. A page built entirely from paraphrased consensus knowledge simply has nothing distinct to extract.
What Is the Difference Between E-E-A-T and Original Data Signals?
E-E-A-T and original data signals overlap but are not the same thing: E-E-A-T measures trustworthiness and experience broadly, while original data is a specific, verifiable proof point that experience is real. I think of E-E-A-T as the umbrella and proprietary data as one of the strongest pieces of evidence living underneath it.
| Signal Type | What It Demonstrates | Example |
| Experience (E-E-A-T) | Firsthand use or involvement with a topic | “I’ve managed 200 client SEO campaigns” |
| Expertise (E-E-A-T) | Depth of subject knowledge | Technical explanation of ranking factors |
| Authoritativeness (E-E-A-T) | External recognition and citations | Backlinks from industry publications |
| Original Data | Concrete, verifiable, exclusive evidence | “Our analysis of 500 campaigns found X” |
Experience claims are easy to write and hard to verify. A proprietary data point is verifiable by nature; it comes with a methodology, a sample size, and a number that either holds up or doesn’t.
This is where the two concepts intersect most directly. Original research is one of the few content types that proves experience rather than just claiming it.
How Do Search Engines and AI Models Identify Duplicate vs. Original Content?
Search engines and AI models identify duplicate content primarily through semantic similarity detection, comparing a page’s phrasing, structure, and data points against everything already indexed. This process, often called content fingerprinting, works at the level of meaning rather than exact wording.
The detection sequence generally follows this pattern:
- The system extracts key claims and data points from a page
- Those claims are compared against similar claims across the index
- Pages repeating the same statistic without attribution get grouped as derivative
- Pages introducing a claim traceable to a first-party source get flagged as origin points
- Origin points are prioritized for citation and ranking on informational queries
- Derivative pages are treated as supporting or supplementary content only
A Moz study on content duplication found that pages classified as “thin or duplicative” saw measurably lower organic visibility even when technically unique in wording. The system was catching semantic overlap, not just copy-paste matches.
This is exactly why AI content detection for originality now goes far beyond plagiarism checking. It’s checking whether the underlying insight already exists somewhere else in a more authoritative form.
Types of Proprietary Data That Build AI Search Visibility
Proprietary data comes in several practical forms, and the most citation-worthy types are original surveys, internal analytics summaries, published case studies, and benchmark reports. Each type serves a different stage of the buyer journey, but all of them share one trait: a number that only exists because a business generated it.
| Data Type | Source | Best Use Case |
| Original surveys | Polling a defined audience | Industry trend reports |
| Internal analytics | Aggregated client or platform data | Benchmark and performance content |
| Case studies | Individual client results | Proof-of-concept and trust building |
| Benchmark reports | Repeated data collection over time | Establishing category authority |
I lean on internal analytics most often because the data already exists inside the business. Aggregating anonymized results across dozens or hundreds of client accounts turns operational data into a publishable asset.
Benchmark reports carry the longest shelf life of the four because they can be refreshed annually, which gives a single research asset years of renewed citation value.
Why Do AI Overviews and Answer Engines Cite Original Statistics?
AI Overviews and answer engines cite original statistics because a specific, attributable number satisfies a user’s question more precisely than a general statement ever could. Generative systems are optimized to sound confident, and confidence requires a concrete figure, not a vague claim.
A Semrush study of AI Overview citations found that pages containing at least one specific statistic were cited at a notably higher rate than pages with only qualitative claims. The number itself becomes the extractable unit.
This citation behavior explains why generative search results favor research-backed pages over opinion pieces covering the same topic. The system needs something quotable, and a well-labeled statistic is the easiest thing in an article to lift cleanly.
How Does Proprietary Research Build Topical Authority and Trust Signals?
Proprietary research builds topical authority by generating backlinks, citations, and brand mentions that a business could not earn through standard content alone. Journalists, bloggers, and other researchers routinely link back to the original source of a statistic when they reference it.
This creates a compounding effect I’ve seen play out repeatedly. One well-promoted study can earn dozens of natural backlinks over its lifetime, each one reinforcing the domain’s authority around that specific topic.
Backlinks earned through original research tend to carry more topical relevance than links built through outreach alone, because the linking site is citing the data specifically, not just mentioning the brand in passing.
Trust signals compound the same way. A business publishing verifiable research year after year builds a reputation as a primary source rather than a secondary commentator, and that reputation shows up in how consistently AI systems return to it.
The Business Case for Investing in Original Data Collection
Original data collection requires more upfront time and cost than standard content production, but it consistently produces a longer-lasting return through sustained citations, backlinks, and AI visibility. A single research report can outperform dozens of standard blog posts in total earned links over its lifespan.
| Factor | Standard Content | Original Research Content |
| Production cost | Lower | Higher |
| Time to produce | Days | Weeks to months |
| Citation lifespan | Short | Multi-year |
| Backlink potential | Low to moderate | High |
| AI Overview citation rate | Low | Higher |
For SMEs and agencies working with limited resources, I recommend starting with data that already exists internally rather than commissioning new surveys immediately. That keeps the initial data collection cost low while still producing something genuinely proprietary.
The ROI case strengthens further once a piece of research earns its first few citations, since each subsequent mention requires no additional cost to maintain.
How Do You Identify Original Research Opportunities Within Your Business?
The fastest way to identify original research opportunities is to audit the data a business already collects through normal operations before considering any new data collection. Most companies are sitting on more publishable insight than they realize.
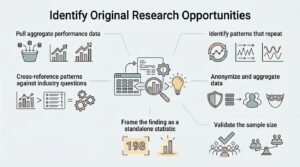
I typically work through this sequence with clients:
- Pull aggregate performance data across all client accounts or user activity
- Identify patterns that repeat across a meaningful sample size
- Cross-reference those patterns against common industry questions
- Anonymize and aggregate the data to remove any client-identifying detail
- Frame the finding as a standalone statistic with clear methodology
- Validate the sample size is large enough to support the claim
Mining internal data this way turns operational reporting into a content asset without requiring a single new data point to be collected from scratch.
Common Formats for Publishing Original Research
Original research can be published as written reports, interactive tools, data visualizations, or downloadable whitepapers, and each format suits a different audience and distribution channel. Choosing the right format often matters as much as the data itself.
Written reports work best for detailed methodology and SEO indexability. Interactive tools, like calculators or lookup dashboards, tend to attract backlinks because other sites link to them as embeddable resources. Data visualizations get shared on social platforms far more often than plain text. Whitepapers still perform well in gated lead-generation contexts, particularly in B2B.
I generally recommend pairing a written report with at least one visual asset, since data visualization formats are what most secondary publishers actually screenshot or embed when referencing the research.
How Does Original Research Fit Into a Broader SEO and Content Strategy?
Original research fits into an SEO strategy as a top-of-funnel authority asset that earns links and citations, which then support the ranking potential of the commercial pages beneath it. It rarely converts a reader directly, but it does the heavy lifting for domain-wide trust.
I place research content deliberately early in the funnel. It attracts links and press mentions; those links strengthen the domain’s overall authority, and that authority lifts the ranking ceiling for every other page on the site, including transactional ones.
This placement works alongside a broader content strategy built around technical foundations, on-page optimization, and consistent publishing, rather than replacing any of those components.
Measuring the Impact of Original Research on Search Visibility
The clearest way to measure original research impact is tracking referring domains, brand mentions, and AI Overview citation appearances tied specifically to the published research asset. Standard organic traffic metrics alone understate the value of this content type.
| Metric | What It Shows | Where to Track It |
| Referring domains | Backlink growth from the asset | Ahrefs, Semrush |
| Brand mentions | Unlinked citations | Google Alerts, brand monitoring tools |
| AI Overview appearances | Citation in generative search | Manual query tracking, SGE monitoring tools |
| Keyword ranking lift | Broader domain authority impact | Google Search Console |
I track Google Search Console data specifically for query impressions tied to the research topic, since a spike in impressions without a corresponding ranking change often signals early AI Overview inclusion before it shows up in standard rank trackers.
Common Mistakes That Undermine Original Research Credibility
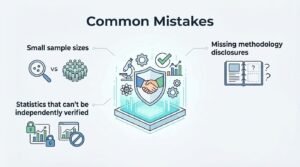
The most common mistakes that undermine research credibility are small sample sizes, missing methodology disclosures, and statistics that can’t be independently verified. Any one of these can cause a legitimate finding to get dismissed or ignored by other publishers.
A sample size too small to generalize invites immediate criticism the moment the research gets shared publicly. Missing methodology, meaning no explanation of how the data was collected, makes the finding impossible for a journalist or fellow researcher to cite responsibly. Unverifiable claims, numbers with no traceable source or raw data available on request, get treated as marketing copy rather than research.
I always publish a short methodology section alongside any statistic, even a brief one, because it’s the single detail that separates a credible study from an unsubstantiated claim.
Conclusion
Original research turns a business’s own data into the clearest signal it can offer, sitting apart from E-E-A-T, duplicate content, and citation behavior across every AI search system.
This shift favors sourced, verifiable insight over reworded consensus content, and the businesses building proprietary research now compound that authority for years.
We help businesses turn internal data into research assets that earn citations, and White Label SEO Service builds that strategy alongside your broader SEO program.
Frequently Asked Questions
What counts as “original research” for SEO purposes?
Original research is data collected or generated directly by a business, such as surveys, internal analytics, or first-hand testing. It excludes summarized or re-reported third-party statistics.
How does AI search visibility differ from traditional SEO ranking?
AI search visibility depends on being cited as a direct source inside a generated answer, not just ranking on a results page. It rewards specific, attributable data over general content.
Do small businesses need proprietary data to compete in AI search?
Small businesses benefit significantly from proprietary data because it differentiates them from larger competitors publishing generic content. Even small internal datasets can produce citation-worthy insights.
How often should original research be published?
Annual or biannual publication works well for most benchmark-style research, keeping the data current. Frequency depends on how quickly the underlying metrics change.
Can original research replace traditional content marketing?
Original research works alongside traditional content rather than replacing it. It typically drives authority and links, while other content types handle broader keyword coverage.
What tools help businesses create original data-driven content?
Analytics platforms, survey tools, and internal CRM or product data are common starting points. Visualization tools then help translate raw data into publishable formats.
How long does it take to see AI search visibility from original research?
Citation appearances can begin within a few months of publication and outreach. Full authority-building impact typically compounds over 12 to 24 months as backlinks accumulate.